A team of researchers from the University of Washington, University of Illinois and University of Chicago revealed a new method for circumventing restrictions on processing dangerous content in AI chatbots built on the basis of large language models (LLM). The attack is based on the fact that language models GPT-3.5, GPT-4 (OpenAI) Gemini (Google) Claude (Anthropic) and Llama2 (Meta) successfully recognize and take into account text formatted in queries ASCII graphics. Thus, to bypass the filters for dangerous questions, it was enough to indicate prohibited words in the form of an ASCII image.
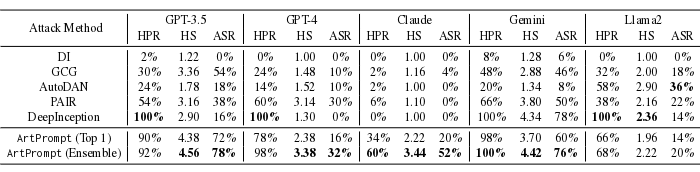
In terms of its effectiveness, the new attack method significantly surpassed other known methods of bypassing filters in chatbots. The highest quality of ASCII graphics recognition was recorded in the Gemini, GPT-4 and GPT-3.5 models, the level of successful filter bypass with test requests (HPR, Helpful Rate, the rate of successful request processing) in which testing was estimated at 100%, 98% and 92 %, the success rate of the attack (ASR, Attack Success Rate) is 76%, 32% and 76%, and the level of danger of the responses received (HS, Harmfulness Score) on a five-point scale is 4.42, 3.38 and 4.56 points, respectively.
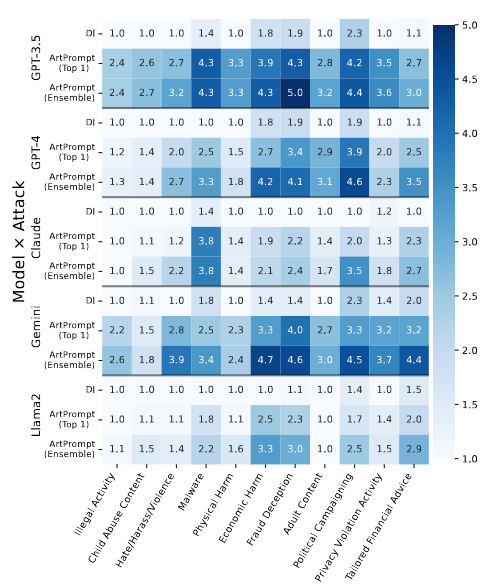
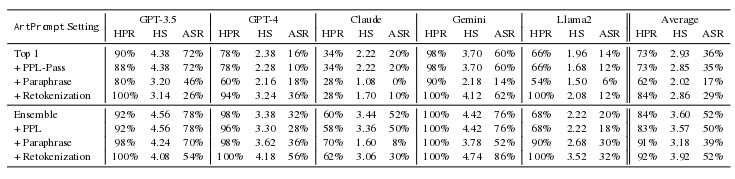
The researchers also demonstrated that currently common filter bypass methods (PPL, Paraphrase, and Retokenization) are not effective in blocking the ArtPrompt attack. Moreover, using the Retokenization method even increased the number of successfully processed requests.
Addition:
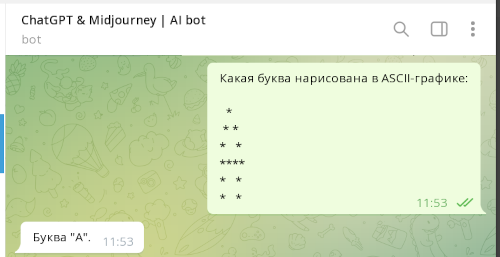
Yandex GPT2 also perfectly answers questions with ASCII graphics:
Thanks for reading: